Claude Haiku 5.5's 100K-Token Cliff Turns $0.10 Into $0.50
Short answer: Claude Haiku 5.5 is $0.10 in / $0.50 out per million tokens for prompts up to 100,000 tokens, and $0.50 / $2.50 above that. Under the cliff it costs exactly what GPT-6 Luna costs on the same message ($1.52 per 1,000 messages at 8K in / 2K out). Above it, Haiku 5.5 costs 5x Luna for the same request. Anthropic's own docs also note the new tokenizer emits roughly 30% more tokens for the same text, which quietly raises the effective rate again.
Anthropic's October 7 launch page for Claude Haiku 5.5 leads with $0.10 per million input tokens. Scroll to the pricing table and the same model charges $0.50 the moment a prompt passes 100,000 tokens. That is five times the sticker, decided by prompt length alone.
Anthropic's cheapest model just became the most interesting one to price. Haiku 5.5 prices 90% below Haiku 4.5 for requests under 100,000 tokens, it is the first Haiku-class model with a user-facing effort setting, and Asana's eval of its agent product reported 30% lower latency. It is also the only Claude 4.6-or-later model Anthropic excludes from its "full 1M context at standard pricing" rule.
Claude Haiku 5.5 pricing: the numbers that matter
Straight from the launch page and the Anthropic pricing table, read today:
| Claude model | Input /1M | Output /1M | Cache read | Cache write |
|---|---|---|---|---|
| Haiku 5.5 (prompt ≤ 100K) | $0.10 | $0.50 | $0.01 | $0.125 |
| Haiku 5.5 (prompt > 100K) | $0.50 | $2.50 | $0.05 | $0.625 |
| Haiku 4.5 | $1.00 | $5.00 | $0.10 | $1.25 |
| Sonnet 5.5 | $2.00 | $10.00 | $0.10 | $2.50 |
Batch work halves both columns: $0.05/$0.25 for short prompts, $0.25/$1.25 above the threshold. The model ships on the Claude Platform, Amazon Bedrock, Google Cloud and Azure, under the ID claude-haiku-5-5.
Two same-day moves from Anthropic are worth noting because they change older math. Sonnet 5.5's cache reads were halved to $0.10 per million tokens (down from $0.20), which Anthropic says cuts about 20% off most agentic work. And Max and Team subscribers now get a monthly API credit pool: $100 for Max 5x, $200 for Max 20x, up to $500 for Team.
What nobody tells you: the cliff is per request, and cache hits don't dodge it
The 100,000-token threshold is not a monthly quota. It is measured per request, and Anthropic counts every input token in the prompt, including cache reads and cache writes. A request over the line pays the higher rates even when most of its prompt came from cache.
That detail breaks the usual advice. "Cache your long system prompt and you're fine" is true for almost every model on the market, and false here: a 120,000-token agent context will be billed at $0.50 input even if 100,000 of those tokens are a cheap cache read.
Here is the same request priced on Haiku 5.5 and GPT-6 Luna, both at their published rates, with no cache:
| Prompt size (2K output) | Haiku 5.5 | GPT-6 Luna | Gap |
|---|---|---|---|
| 25K tokens | $0.0035 | $0.0035 | 1.0x |
| 100K tokens | $0.0110 | $0.0110 | 1.0x |
| 150K tokens | $0.0800 | $0.0160 | 5.0x |
| 250K tokens | $0.1300 | $0.0260 | 5.0x |
| 300K tokens | $0.1550 | $0.0615 | 2.5x |
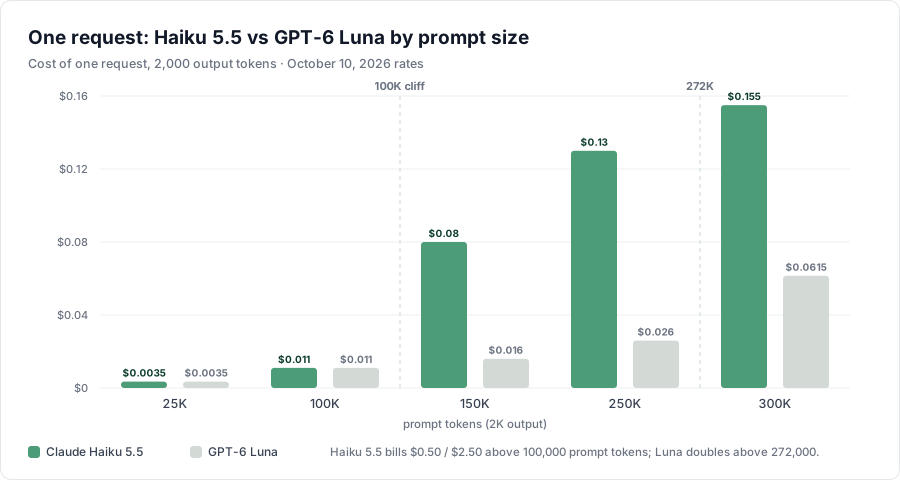
Luna has a cliff of its own, at 272,000 tokens, but it only doubles and only above a point most chats never reach. Between 100K and 272K, Haiku 5.5 is five times the price of the model it ties with below 100K.
If you summarize long documents, run RAG over big contexts, or keep a fat agent memory in one request, that is the whole ballgame. Move 1,000 such requests per month from Luna to Haiku 5.5 and you add $64 a month for the privilege.
Haiku 5.5 vs GPT-6 Luna: the identical sticker price
Anthropic priced Haiku 5.5 at exactly GPT-6 Luna's rates. Not similar: $0.10 input, $0.50 output, $0.01 cached input, $0.125 cache write. So we ran the profile we use for every cost post, one chat message at 8,000 input tokens and 2,000 output, with 40% of the input read from cache and 5% written to it:
| Model | Per 1,000 messages |
|---|---|
| Claude Haiku 5.5 | $1.52 |
| GPT-6 Luna | $1.52 |
| DeepSeek V4.1-Flash (off-peak) | $1.87 |
| Gemini 3.5 Flash-Lite | $6.42 |
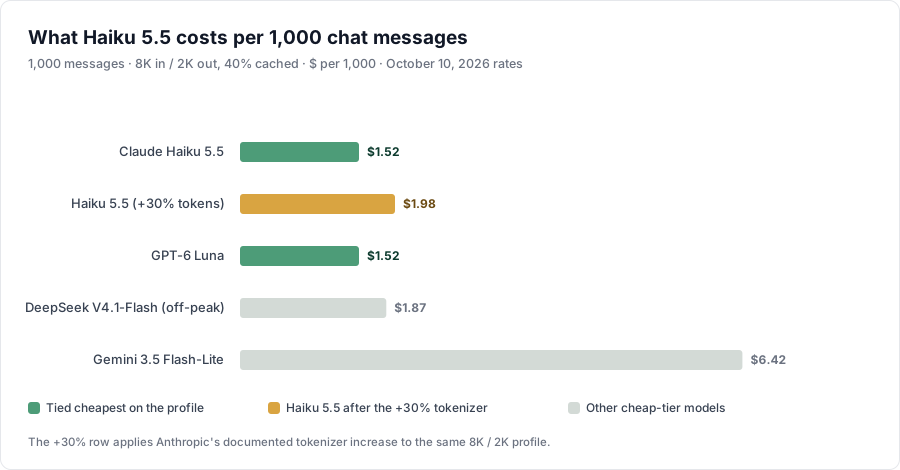
Then the caveat Anthropic prints on its own pricing page: Claude 4.7 and later models use a newer tokenizer that produces approximately 30% more tokens for the same text. If your content lands on that average, Haiku 5.5's identical $0.10/$0.50 is effectively $0.13/$0.65 against Luna's $0.10/$0.50. On our profile that moves Haiku 5.5 from $1.52 to $1.98 per 1,000 messages, which makes it the priciest of the sub-$2 models, ahead of Luna and DeepSeek. Gemini 3.5 Flash-Lite still costs more at $6.42, but that is a different purchase.
I am not going to pretend the tokenizer delta is precise. Anthropic says the increase depends on the content and the workload shape, and we cannot verify token counts for your text without your text. What we can say is that the direction is documented by the vendor, it is not small, and no launch coverage we read mentioned it alongside the price.
Which Should You Choose?
| If you… | Pick |
|---|---|
| Keep prompts under 100K tokens and want Claude's tooling | Haiku 5.5 — same price as Luna, better Terminal-Bench (39.2% vs 16.4%) |
| Summarize or retrieve over very long contexts | GPT-6 Luna — 5x cheaper per request above 100K |
| Run cheap batch jobs | Haiku 5.5 Batch at $0.05/$0.25, or Luna Batch at $0.05/$0.25 — still a tie |
| Need the lowest possible bill and can live with peak-hour pricing | DeepSeek V4.1-Flash at $0.15/$0.60 off-peak |
| Do serious agentic coding | Neither. Sonnet 5.5 or Opus 5.5, and Haiku 5.5 as the subagent |
The last row is Anthropic's own framing, and it is honest: the launch page shows Haiku 5.5 at 39.2% on Terminal-Bench 4.0 against Sonnet 5.5's 70.6%. Compaction, classification, routing, subagents — that is where this model earns its price.
What you give up
- Haiku 5.5 is not a Sonnet replacement, and Anthropic says so. If your agent needs to plan a ten-step refactor, the cheap model will burn more tokens doing it badly.
- The 30% tokenizer figure is an average from Anthropic's own comparison of Haiku 4.5 to Haiku 5.5. We cannot measure it against OpenAI's tokenizer for arbitrary text, and nobody publishes a token-by-token cross-vendor count.
- DeepSeek's off-peak rate only holds outside 01:00–04:00 and 06:00–10:00 UTC on weekdays. Peak hours double the rate to $0.30/$1.20.
- Gemini 3.5 Flash-Lite's $0.30/$2.50 is the current number, and Google's Flash line doubles on January 1, 2027. Compare against the 2027 column, not just today's.
- We did not test output quality. Every benchmark here comes from the vendor's own launch page, and vendor benchmarks are marketing until someone independent reproduces them.
FAQ
Is Claude Haiku 5.5 cheaper than GPT-6 Luna? At or below 100,000 prompt tokens they cost exactly the same: $0.10 input, $0.50 output per million tokens. Above 100,000 tokens, Haiku 5.5 charges $0.50/$2.50, which makes it five times Luna's price for the same request.
Does prompt caching help on Haiku 5.5? Yes, but only under the threshold. Cache reads cost $0.01 per million tokens up to 100,000 prompt tokens and $0.05 above it, and the prompt length that decides which rate applies counts cache reads at full length.
What is the effort setting on Haiku 5.5? It is Anthropic's control for trading cost against intelligence, and Haiku 5.5 is the first Haiku-class model to expose it. Lower effort means fewer reasoning tokens, which lands directly on your bill at the output rate.
Should I switch from Haiku 4.5? For short prompts, yes: Haiku 5.5 prices 90% below Haiku 4.5 and scores 1620 vs 735 on GDPval-AA v2.1. For very long prompts the discount shrinks to 50%, but that still beats the old rate.
If you want to price your own mix, the arithmetic above is reproducible on any vendor's rate card — 8,000 input tokens (4,400 uncached, 3,200 cache reads, 400 cache writes) and 2,000 output tokens per message — and the profiles in what the ChatGPT API costs per month are the same shape we used here. Adding your Anthropic key takes about a minute with the setup guide, and you can keep Luna in the same conversation and compare answers side by side. If you are still deciding whether any API route beats a $20 subscription, we ran that math too.
Start your free trial → — 7 days, all providers, no credit card required.
The workspace is $2/month or $39 once — AI providers always bill your key directly at their own rates.
See pricingThe Multimodel Journal
Get the latest AI insights, model comparisons, and product updates delivered to your inbox.
Subscribe